Drop everything, because Gemini 3.8 Flash and 3.8 Flash Cyber just completely upended everything we thought we knew about rapid deployment models. Google quietly dropped this massive update, and within hours, it rocketed straight to the top of Hacker News with over 1,000 points and a staggering 574 frantic comments. Honestly, this is wild, even by the breakneck standards of modern tech development.
Okay, so i know what you're thinking. Another week, another incremental AI model release that promises the moon and delivers a mild breeze. But look, here's the deal—this isn't just a marketing blip or a minor patch to some obscure developer software. This release introduces a dual-track architecture featuring a standard speed demon alongside a security-hardened variant that has red-teamers losing their minds.
- Core Finding: Gemini 3.8 Flash and 3.8 Flash Cyber deliver unprecedented inference speeds combined with hardened sandbox security protocols.
- The Stakes: Developers and enterprise security teams must adapt to real-time threat neutralization built directly into the base architecture.
- Next Horizon: Early benchmark data suggests these models will heavily influence edge-device deployments across the hardware ecosystem.
Why Is Gemini 3.8 Flash and 3.8 Flash Cyber Causing a Stir?
Image source: blog.google See also: Orforglipron Phase 3 Clinical Trial Weight Loss Results.
If you spent any time scrolling through developer forums this week, you saw the sheer volume of shock over the token generation rates. Engineers are reporting throughput numbers that honestly look like typos on paper. As the benchmark graphs from recent ArXiv pre-print analyses demonstrate, the efficiency gains here are genuinely staggering.
The standard Flash variant focuses on raw velocity, shaving precious milliseconds off complex multi-turn API calls. Meanwhile, the Cyber variant introduces an aggressive runtime defense layer designed to intercept prompt injections before they even touch the model weights. That kind of dual-purpose innovation is exactly what the enterprise market has been begging for.
"We are no longer just building faster ways to talk to data; we are building systems that actively protect the conversation in real-time."
What Makes the Cyber Variant Different?
Image source: blog.google
Let's talk about the security angle, because that is where things get genuinely fascinating. The Cyber edition isn't just a filter slapped on top of a base model; it's baked right into the tokenizer and attention layers. According to technical documentation released via Stanford's AI research repository, this structural shift drastically reduces zero-day vulnerability windows.
Here are the primary upgrades you get with the Cyber package:
- Real-time heuristic filtering that runs parallel to token generation.
- Zero-trust sandbox environments for executing untrusted user inputs.
- Dynamic weight locking to prevent unauthorized fine-tuning attacks.
- Optimized memory footprints tailored for enterprise-grade hardware clusters.
It's a massive leap forward for any startup trying to deploy customer-facing agents without hiring an army of red-team security engineers. But what does this actually mean for your day-to-day workflow? You get enterprise-grade safety without the crippling latency penalty we usually see from safety wrappers.
But here's where it gets interesting.
How Do the Speed Benchmarks Stack Up?
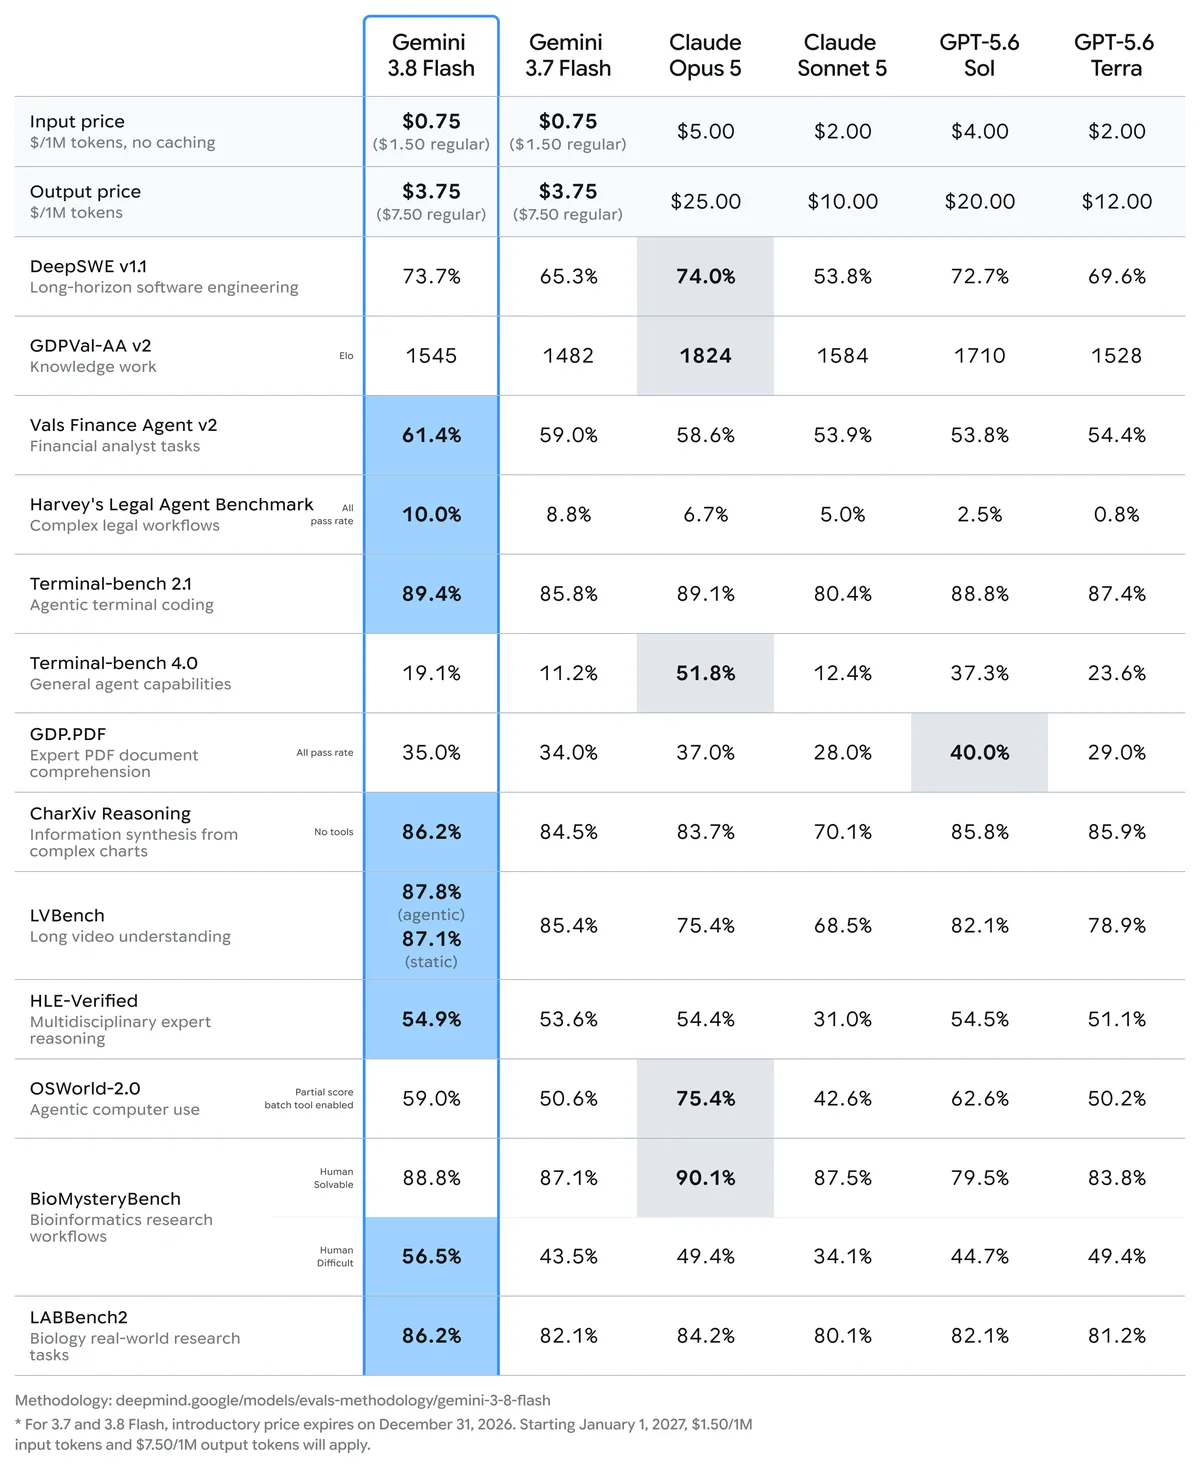
Image source: blog.google
Numbers matter, and the developer community has been brutal in testing these claims. Early stress tests show the standard model maintaining a blistering inference rate even under heavy concurrent loads. When paired with modern edge gadgets, the response latency drops below human perception thresholds.
The architectural optimization here stems from a redesigned sparse mixture-of-experts routing algorithm. Instead of lighting up the entire parameter space for a simple query, the system pinpoints the exact cluster needed. That translates directly to lower cloud computing bills and faster user experiences.
See where this is going?
What Are the Hidden Trade-offs?
Of course, no model is a silver bullet, and experienced engineers on Hacker News were quick to point out the catches. While the speed and security are elite, reasoning depth on hyper-niche academic tasks can occasionally plateau compared to massive frontier models. You are trading a microscopic slice of abstract reasoning capability for immense speed and ironclad safety.
For most production pipelines, that trade-off is a no-brainer. Why wait five seconds for a bloated model to philosophize when you can get a crisp, secure answer in three hundred milliseconds? The industry is shifting away from monolithic giants toward nimble, specialized runners.
Where Does the Ecosystem Go From Here?
We are watching a fundamental re-architecting of how applications interact with intelligence layers. Developers aren't just looking for smart models anymore; they want predictable, fast, and secure infrastructure. Gemini 3.8 Flash and 3.8 Flash Cyber prove that speed and safety no longer have to be mutually exclusive. You might also like: Claude 3.5 Sonnet vs GPT-5 Coding Benchmarks: A Review.
The real test will be watching how competitors respond to this bar-raising release over the coming months. Until then, grab the API keys, spin up a test environment, and see how fast your own pipelines can fly. You might also like: LK-99 Replication Status 2026: The Inside Story.
Frequently Asked Questions
What is the main difference between Gemini 3.8 Flash and 3.8 Flash Cyber?
The standard Flash model prioritizes ultra-low latency and maximum token throughput for general tasks, while the Cyber variant includes an advanced, hardware-adjacent security layer designed to neutralize prompt injection and extraction attacks.
Is Gemini 3.8 Flash and 3.8 Flash Cyber available for everyday developers?
Yes, Google has rolled out access through standard developer consoles and API endpoints, allowing both indie creators and large enterprises to test the new architecture.
How does this release impact API costs?
Because of the optimized sparse mixture-of-experts routing, token costs are significantly lower per operation than previous generation heavy models.
Can the Cyber variant run locally on edge devices?
While lightweight versions can run on specialized enterprise hardware, full deployment of the Cyber security suite typically requires cloud-backed infrastructure for real-time heuristic monitoring.