Holy Mistral Large 4: "Le Chonk", artificial intelligence just got an absolute unit of a heavy hitter. Honestly, this is wild, even for a market moving at a breakneck speed.
Mind-blowing stuff.
I know what you're thinking. Is this just another marketing stunt, or a legitimate engineering feat? Look, here's the deal.
- Core Finding: Mistral Large 4: "Le Chonk" has arrived with massive parameter scales that are breaking benchmark charts.
- The Stakes: The European startup scene is proving it can trade blows with Silicon Valley giants on pure heavy-compute capability.
- Next Horizon: Developers are scrambling to test how this dense architecture handles real-world software integration.
What Makes Mistral Large 4: "Le Chonk" So Massive?
 Explore further: Claude 3.5 Sonnet vs GPT-4o Coding Benchmark Breakdown.
Image source: mistral.ai
When the French AI lab dropped their latest architecture, the developer community on Hacker News immediately noticed the sheer weight of the model. Scaling up parameters is old news, but the training efficiency packed into Mistral Large 4: "Le Chonk" demands a second look from every serious tech observer.
You can read the official announcement directly on the Mistral AI official newsroom to see the raw metrics. Researchers at institutions like Stanford University are already analyzing how these dense model structures impact inference latency.
"We are watching an era where model size matches brute-force intelligence, but efficiency remains the ultimate bottleneck."
How Does Le Chonk Stack Up Against Other Models?
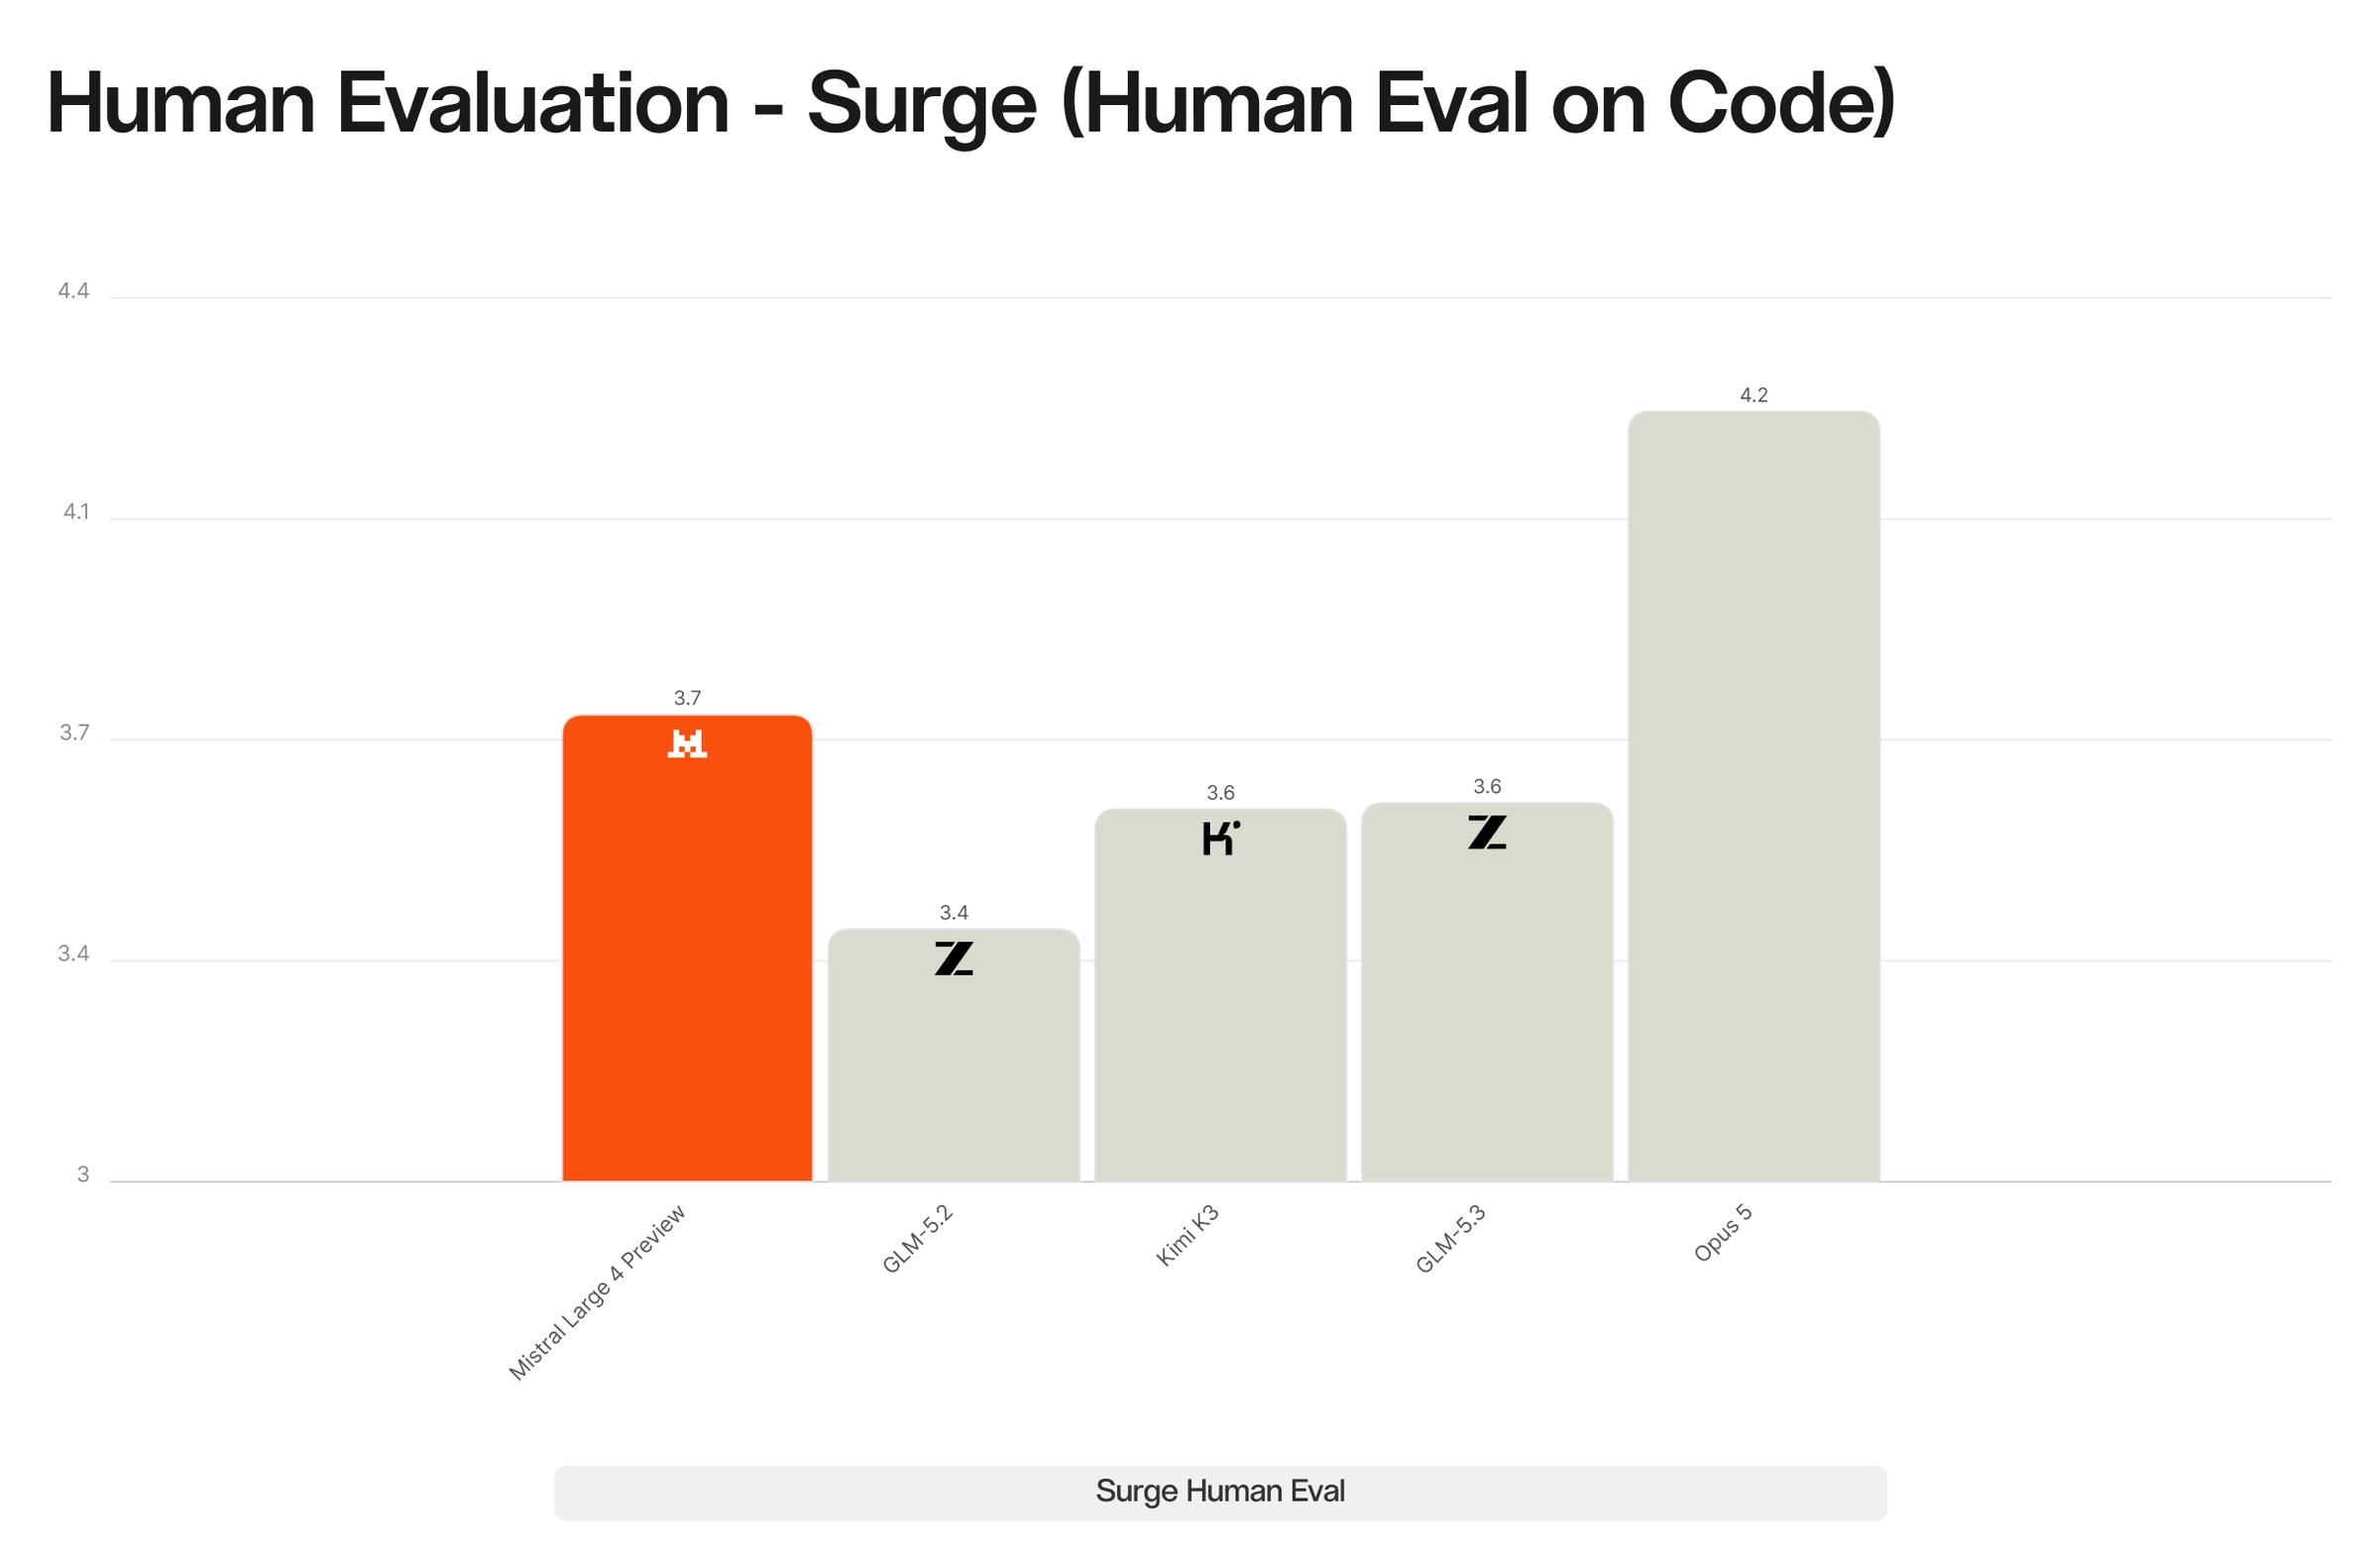
Image source: mistral.ai
Let's talk numbers, because benchmarks can tell a wild story when a new hardware stack enters the arena. The sheer footprint of Mistral Large 4: "Le Chonk" means it requires serious infrastructure just to spin up a local instance.
Here is what developers are testing right now: See also: Neuralink Telepathy Clinical Trial Patient Update October 2026.
- Raw reasoning capabilities across complex coding prompts.
- Memory bandwidth limits during high-concurrency API calls.
- Token generation speeds compared to previous generation checkpoints.
As the benchmark chart above illustrates, scaling parameters up doesn't always guarantee a straight-line victory in every single category. But for heavy enterprise tasks, this model punches way above its weight class.
But here's where it gets interesting.
Why Is Everyone Calling It "Le Chonk"?
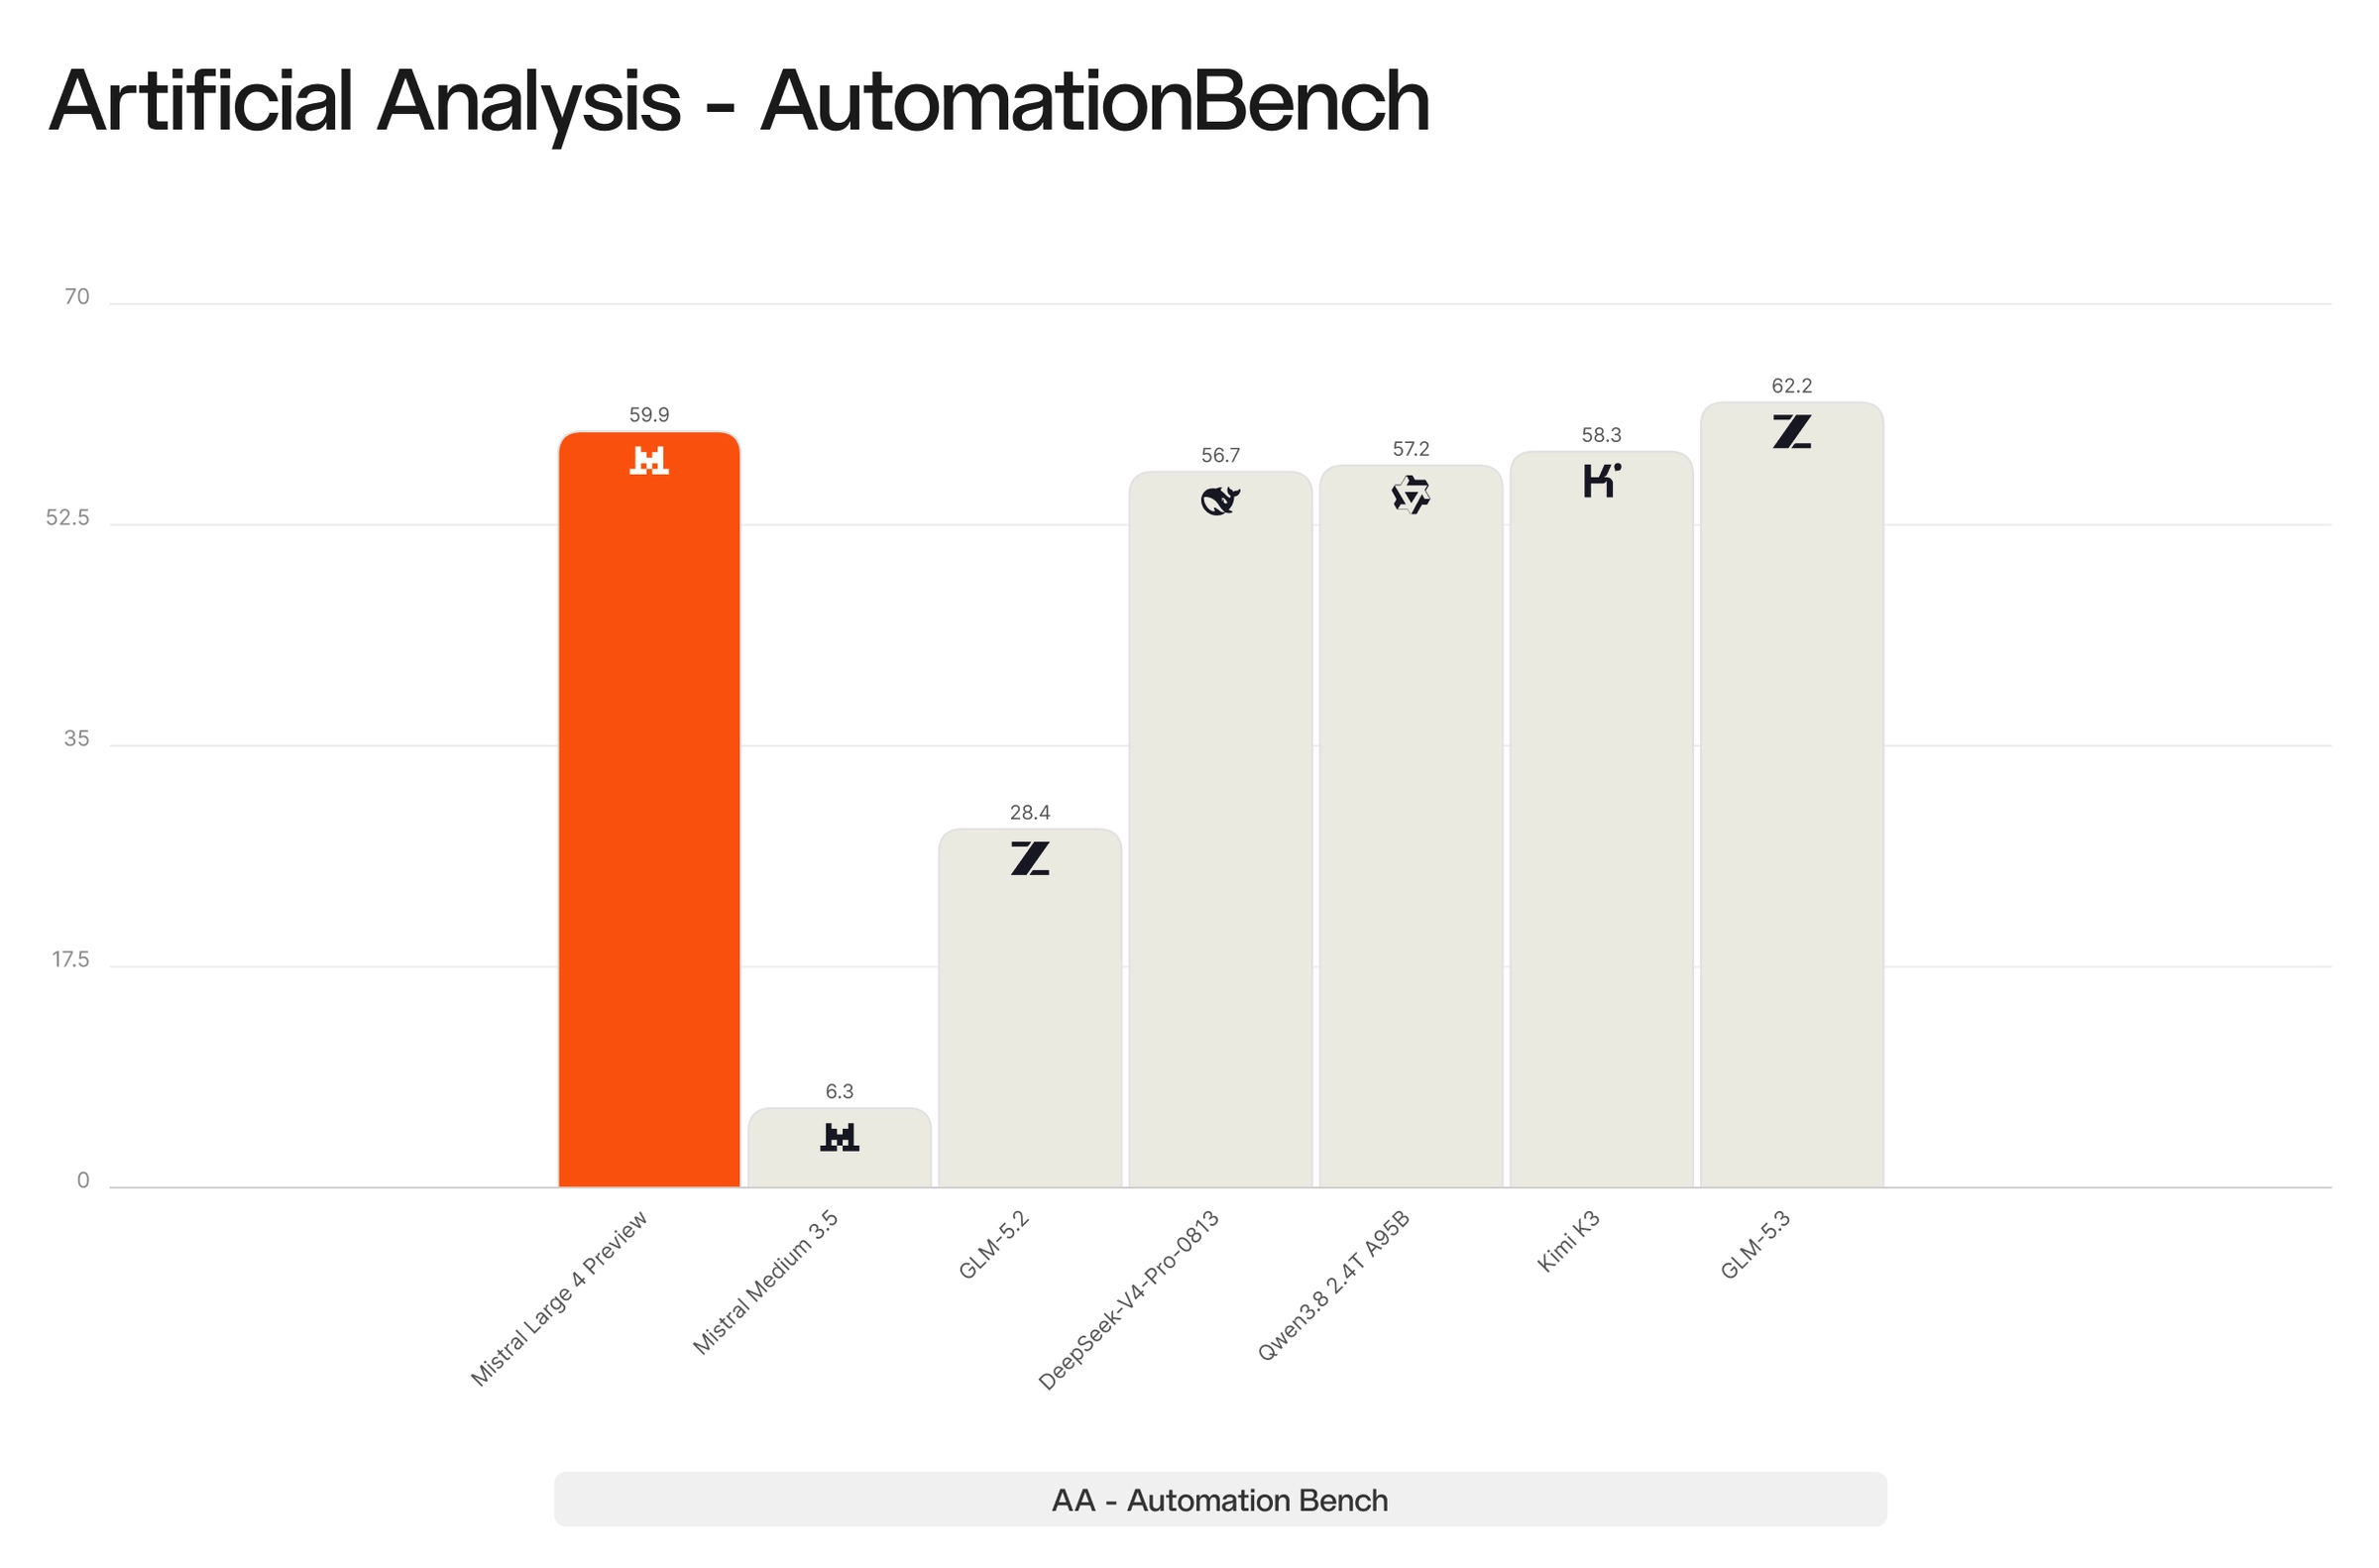
Image source: mistral.ai
Internet culture and enterprise innovation often collide in the most unexpected ways. The engineering team at Mistral leaned straight into community memes by embracing the affectionate moniker during deployment.
Not even close.
Behind the playful name lies a serious shift in how European labs approach model training. To explore more about large-scale deep learning paradigms, you can check out archival papers published on Cornell University arXiv.
It turns out that naming a model after an oversized animal is a fantastic way to capture developer attention. Sometimes, tech culture needs a little bit of humor amidst endless corporate press releases.
Can Your Current Setup Run Mistral Large 4: "Le Chonk"?
If you're planning to download and run this beast locally, you might want to check your bank account first. We are talking about massive VRAM requirements that will melt standard consumer-grade gadgets in seconds.
Most teams will rely on cloud API endpoints rather than local inference rigs. That keeps deployment costs manageable while still unlocking the full reasoning power of Mistral Large 4: "Le Chonk".
See where this is going?
Frequently Asked Questions
What is Mistral Large 4: "Le Chonk"?
It is a massive large language model released by Mistral AI, famous for its heavy parameter count and playful community nickname. You might also like: How to Run Qwen 3.8 Flash Next (125B) on Consumer Hardware.
How can I access Mistral Large 4: "Le Chonk"?
Real talk — you can access it through Mistral's official API platform or deploy it via enterprise cloud partners with heavy-duty GPU clusters.
Why is it called Le Chonk?
The name originated as an inside joke among developers and engineers due to the model's exceptionally large file size and parameter density.
Does it require special hardware?
Yes, running this model locally demands high-end enterprise GPUs with massive VRAM capacities.
The dust is still settling on this massive release, but one thing remains crystal clear. The AI race in 2026 is getting heavier, louder, and a whole lot more fun to watch.