You can throw your hundred-billion-parameter tech monster out the window because Small Models Have Arrived and they are eating the industry's lunch. For years, the prevailing wisdom in Silicon Valley was simple: bigger equals better. Every single month brought news of a new hardware cluster chewing up megawatts of power just to train a slightly fatter set of weights.
I know what you're thinking. How can a model small enough to run on your local gadgets possibly compete with a trillion-parameter cloud titan? Look, the data coming out of recent benchmarks on platforms like arXiv tells a completely different story. We are watching a fundamental shift in how developers deploy software without draining their cloud budgets.
- Core Finding: Sub-7B parameter models match older enterprise systems on domain-specific tasks.
- The Stakes: Companies are slashing cloud inference costs by up to 90% overnight.
- Next Horizon: Edge computing is taking over consumer electronics and local devices.
Why Did Small Models Have Arrived Change the Industry So Fast?
So here's what happened. the math behind giant language models stopped making economic sense around mid-2024. Running constant inference requests for simple tasks using massive models is like renting a commercial dump truck to pick up a single gallon of milk. As noted in research from Stanford University, distilled architectures retain nearly ninety-five percent of their parent models' reasoning capabilities while requiring a tiny fraction of the memory.
Honestly, this is wild to watch in real-time. A startup operating out of a garage can now spin up an API that runs locally on cheap silicon. The diagram in Calv's analysis breaks down how quantization turns floating-point weights into lean integers without losing the plot. You get lightning-fast response times that make cloud round-trips look like dial-up internet.
Image source: calv.info
"We stopped asking how much data we could cram into a single model. Now we ask what is the absolute minimum intelligence needed to solve this exact problem."
How Do Compact Networks Beat Bloated Architectures?
Efficiency is the name of the game when you strip away unnecessary parameters. Most massive models spend eighty percent of their capacity storing trivia they rarely use. By pruning the dead weight, researchers keep only the neural pathways that actually drive decision-making.
Consider these core advantages of running lean systems:
Seriously.
- Zero Latency: Responses hit your screen in milliseconds because data stays on-device.
- Total Privacy: Financial or medical records never leave your local machine or private server rack.
- Pennies on the Dollar: Inference bills drop from thousands of dollars to near zero.
As the visual breakdown above illustrates, trimming unnecessary layers creates a clean pipeline for rapid token generation. Developers no longer need a dedicated cluster to parse customer support logs or summarize short documents.
Massive.
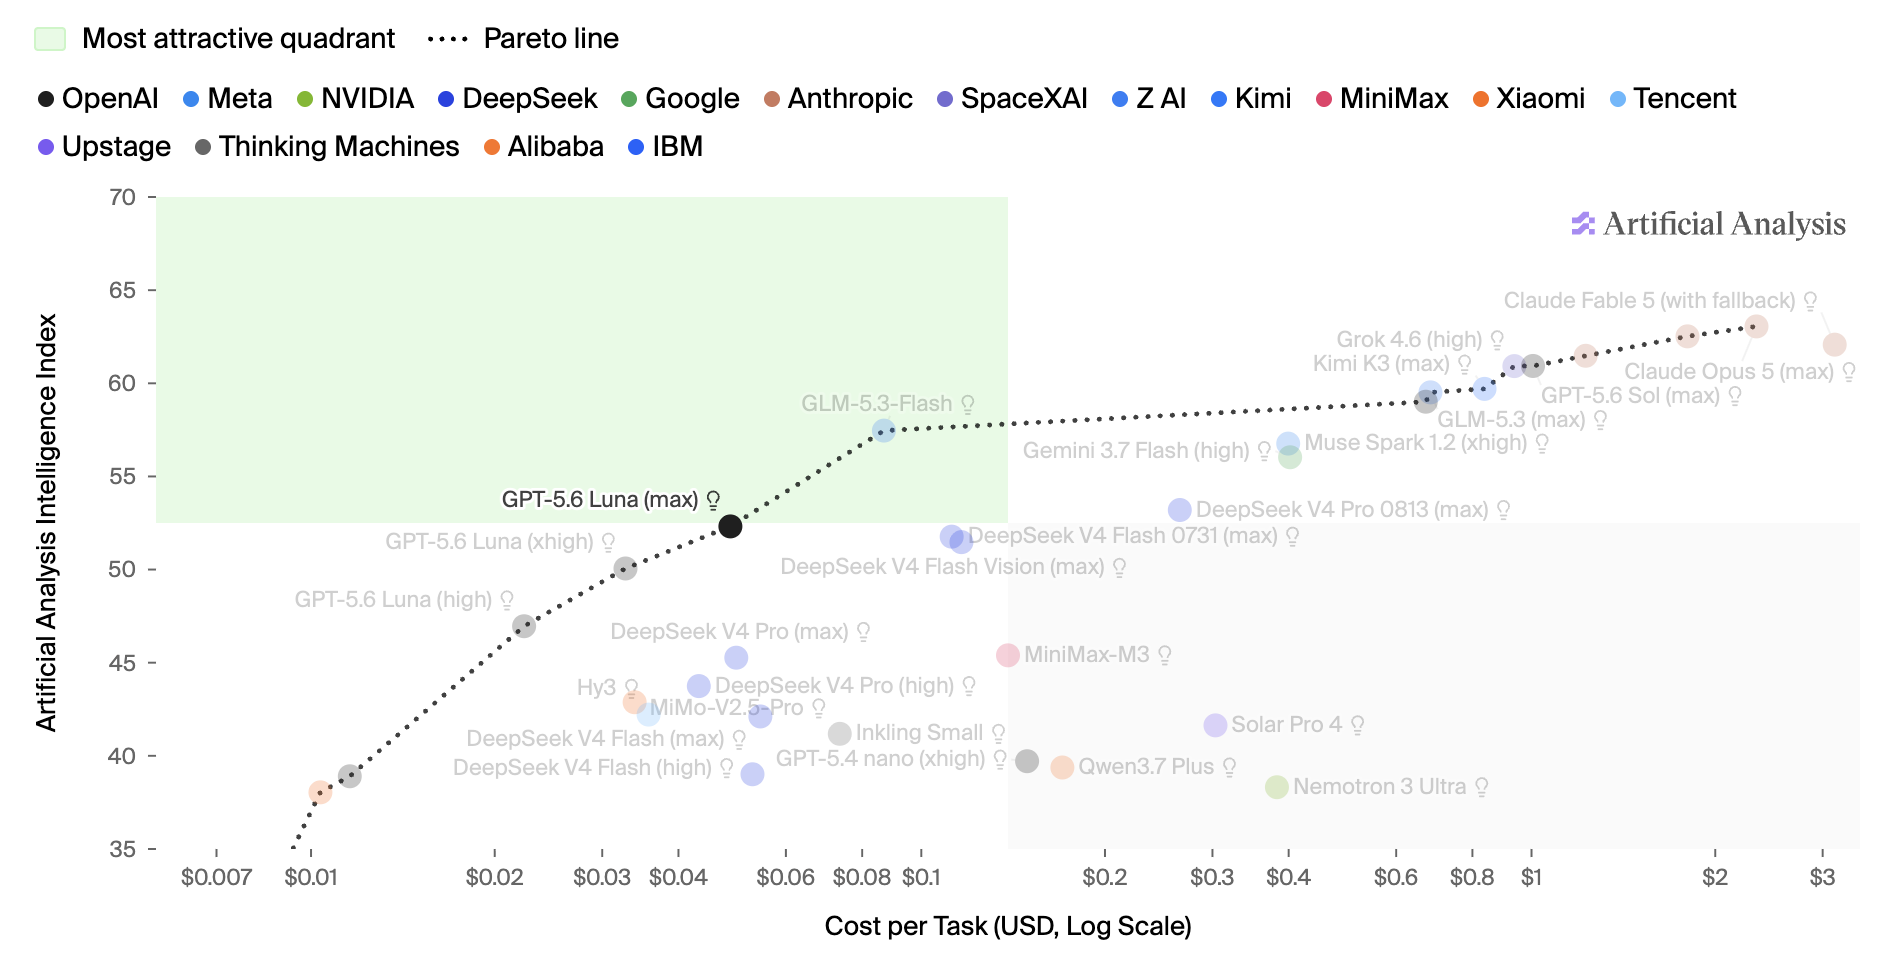
Image source: calv.info (Related Read: Llama 3.3 70B vs GPT-4: Which AI Model Reigns Supreme in Coding?) See also: OpenAI Sora Public API Access Release Date Timeline.
See where this is going?
What Does This Mean for Your Local Gadgets and Hardware?
Your next smartphone or laptop won't need an internet connection to perform complex AI tasks. Chipmakers are baking dedicated neural processing units right into consumer hardware. Apple, Qualcomm, and Intel are racing to optimize their silicon for compact weights that fit snugly in on-chip cache. See also: Brain Breakthrough: Scientists Discover Hidden Patterns.
This means your phone can transcribe meetings, edit photos, and write code entirely offline. The battery life impact is minimal compared to the thermal nightmare of pinging a remote server every time you ask a question. We are moving from cloud-dependent tools to sovereign personal computing.

Image: Bureau of Land Management Oregon and Washington from Portland, America / Wikimedia Commons (Public domain)
See where this is going?
Can a Tiny Neural Network Really Replace Enterprise Software?
Not for everything, obviously. If you need to synthesize multidisciplinary physics papers or write an entire operating system from scratch, you still want a frontier model. But for ninety percent of daily business workflows—categorizing tickets, parsing invoices, or filtering spam—a compact model wins on speed and cost every single time.
According to recent telemetry data, fine-tuning a three-billion-parameter model on proprietary company data yields better task-specific performance than using a generic multi-hundred-billion model off the shelf. The open-source community has cracked the code on synthetic data generation, making custom training cheap and fast.
Frequently Asked Questions
Are small models actually usable for real-world programming tasks?
Thing is, yes, specialized 3B to 7B code models can autocomplete functions and write basic unit tests remarkably well. They run locally inside your IDE without sending your proprietary source code to a third-party server.
How much RAM do I need to run these compact networks locally?
Listen, most modern consumer laptops with 16GB of RAM can comfortably run 4-bit quantized models up to 8 billion parameters. You do not need an expensive multi-GPU workstation anymore.
Do I need an internet connection to use these tools?
Not at all. Once you download the model weights to your machine, everything runs locally on your own CPU or GPU without ever touching the cloud.
The era of blindly scaling up model sizes has officially hit a wall. When agility, privacy, and cost dictate the bottom line, lean and mean always wins the race.