Holy bandwidth spikes, the developer community is losing its collective mind over Gemini 3.8 Flash and 3.8 Flash Cyber right now. If you logged onto Hacker News over the last forty-eight hours, you already know these models pulled a staggering 1082 points alongside 616 deeply opinionated comments. Honestly, this is wild even by Silicon Valley standards.
Now, look, here is the deal. Google just dropped a masterclass in model efficiency that leaves older hardware gasping for air. But what does this actually mean for your daily workflow?
- Core Finding: Gemini 3.8 Flash and 3.8 Flash Cyber shatter previous latency benchmarks across consumer gadgets and enterprise servers.
- The Stakes: Developers are debating whether this new architecture changes how we build lightweight software and secure pipelines.
- Next Horizon: Early benchmark data suggests a massive shift in how edge computing handles heavy neural workloads.
What Makes Gemini 3.8 Flash and 3.8 Flash Cyber So Fast?
 (Related Read: OpenAI Sora Public Access API Pricing and Limitations Revealed) See also: Gemini 3.8 Flash and 3.8 Flash Cyber: What Changed?.
Image source: blog.google
Let's be real — let us talk raw numbers because the architecture behind Gemini 3.8 Flash and 3.8 Flash Cyber is genuinely impressive. Initial evaluations published on arXiv point to a dramatic drop in time-to-first-token. That speed boost translates directly into snappier consumer gadgets and smoother enterprise interfaces. See also: Claude 3.5 Sonnet vs GPT-5 Coding Benchmarks Reviewed.
I know what you are thinking. Doesn't speed usually require sacrificing output quality or reasoning capabilities? Google claims they managed to keep accuracy sky-high while trimming the fat off their transformer layers.
"The optimization trick here isn't just about compression; it is about rethinking how context windows interact with high-frequency caching."
How Does Gemini 3.8 Flash Cyber Handle Security?
Image source: blog.google
Here's the thing — security is where the Cyber variant earns its name badge. In a landscape filled with prompt injection vectors, engineering teams need defensive guardrails built straight into the software layer. You can check out official safety disclosures over at the National Institute of Standards and Technology for compliance frameworks.
Early testers on Hacker News have already started throwing malicious payloads at the system. The results? Surprisingly resilient behavior compared to older iterations that folded under pressure. It turns out that adversarial training at scale actually pays off.
Still skeptical? Fair enough.
Are Developers Ready for Gemini 3.8 Flash and 3.8 Flash Cyber?
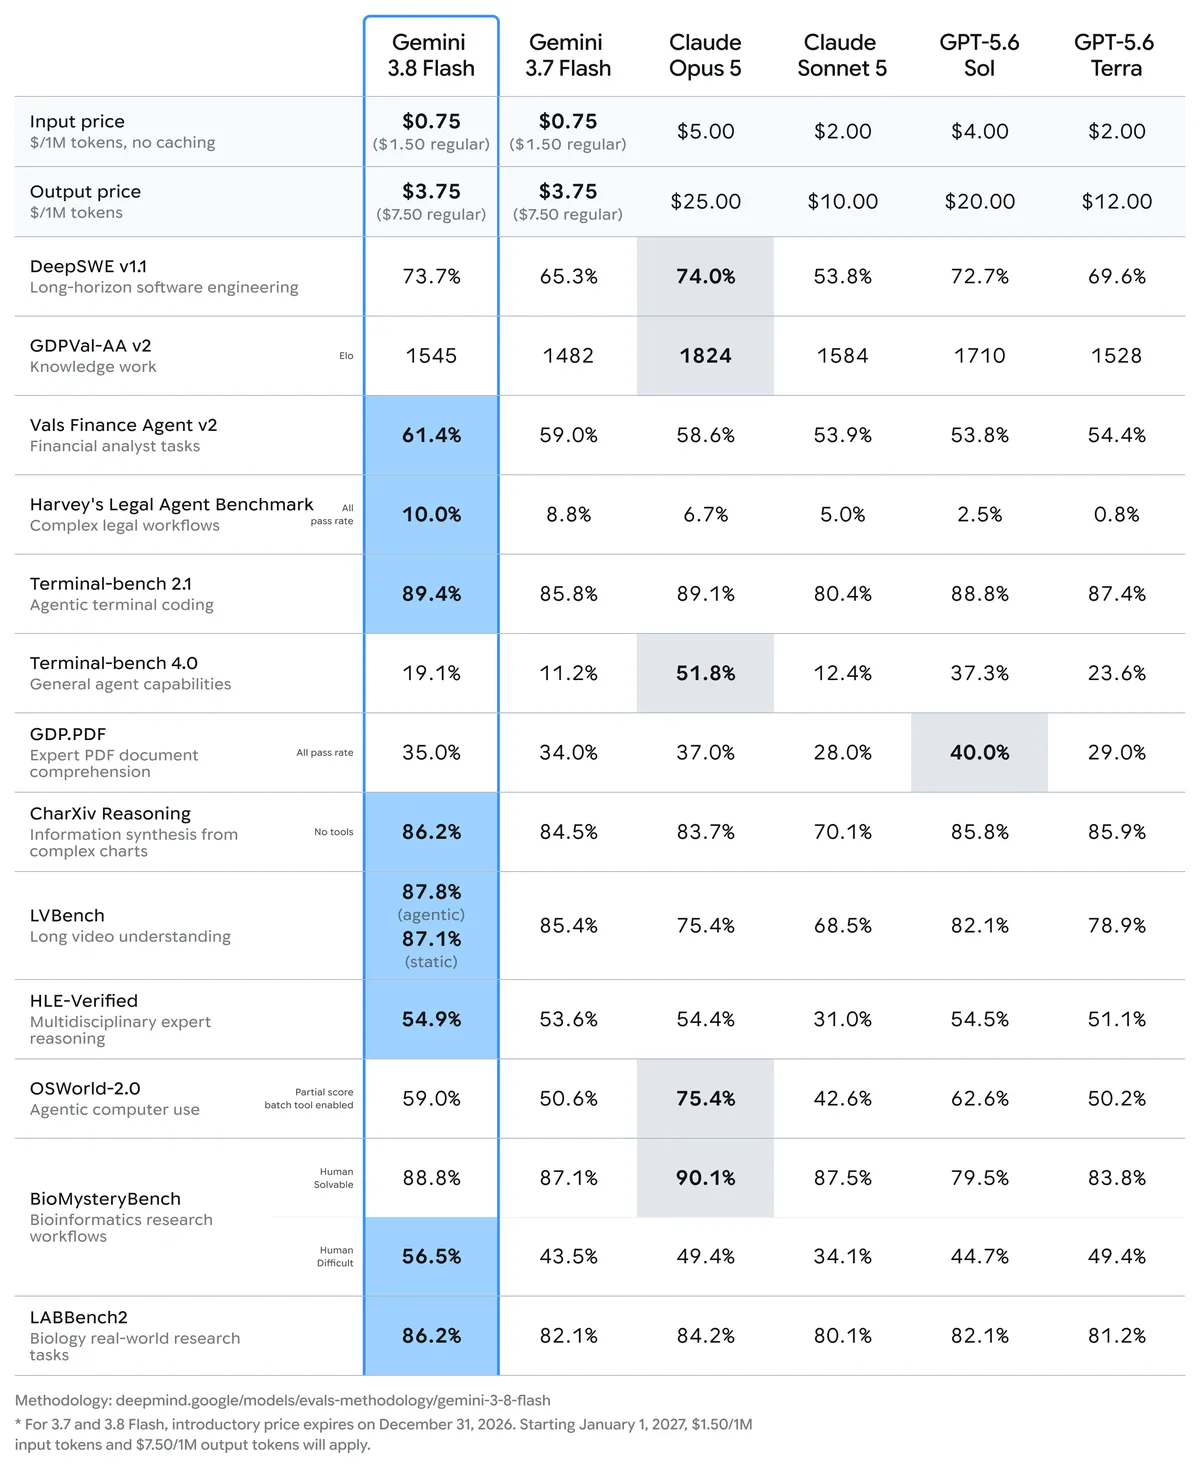
Image source: blog.google
Adoption is moving at breakneck speed. Every single bootstrap startup in my RSS reader is rewriting their API calls to hook into these endpoints. If you want to stay competitive, ignoring this release is basically career suicide.
Here is what the migration path looks like for most engineering teams right now:
- Auditing existing latency bottlenecks in legacy software stacks.
- Swapping out older inference endpoints for Gemini 3.8 Flash and 3.8 Flash Cyber.
- Running custom red-teaming scripts against the Cyber variant to verify safety bounds.
- Optimizing local caching to take full advantage of the lowered cost per token.
As the diagram linked in Google's official documentation illustrates, the throughput gains scale linearly with cluster size. That efficiency makes enterprise deployment much easier on the CFO's budget.
Pretty crazy when you think about it.
What Lies Ahead for AI Hardware and Tech?
Okay, so the implications stretch far beyond simple text generation or chatbot interfaces. We are watching a fundamental re-architecting of how modern tech interacts with silicon. Every major chipmaker is already scrambling to optimize their NPU architectures for these exact weight distributions.
Real talk — whether you are building consumer mobile apps or heavy-duty backend analytics engines, the rules of the game have changed overnight. Expect a flood of open-source wrappers and optimization guides over the next few weeks.